Control Group
Variant Group
Statistical significance
Updates as you typeHumblytics runs this same check on every live A/B test as results come in, scored on conversions or on revenue. See A/B testing →
What your result looks like
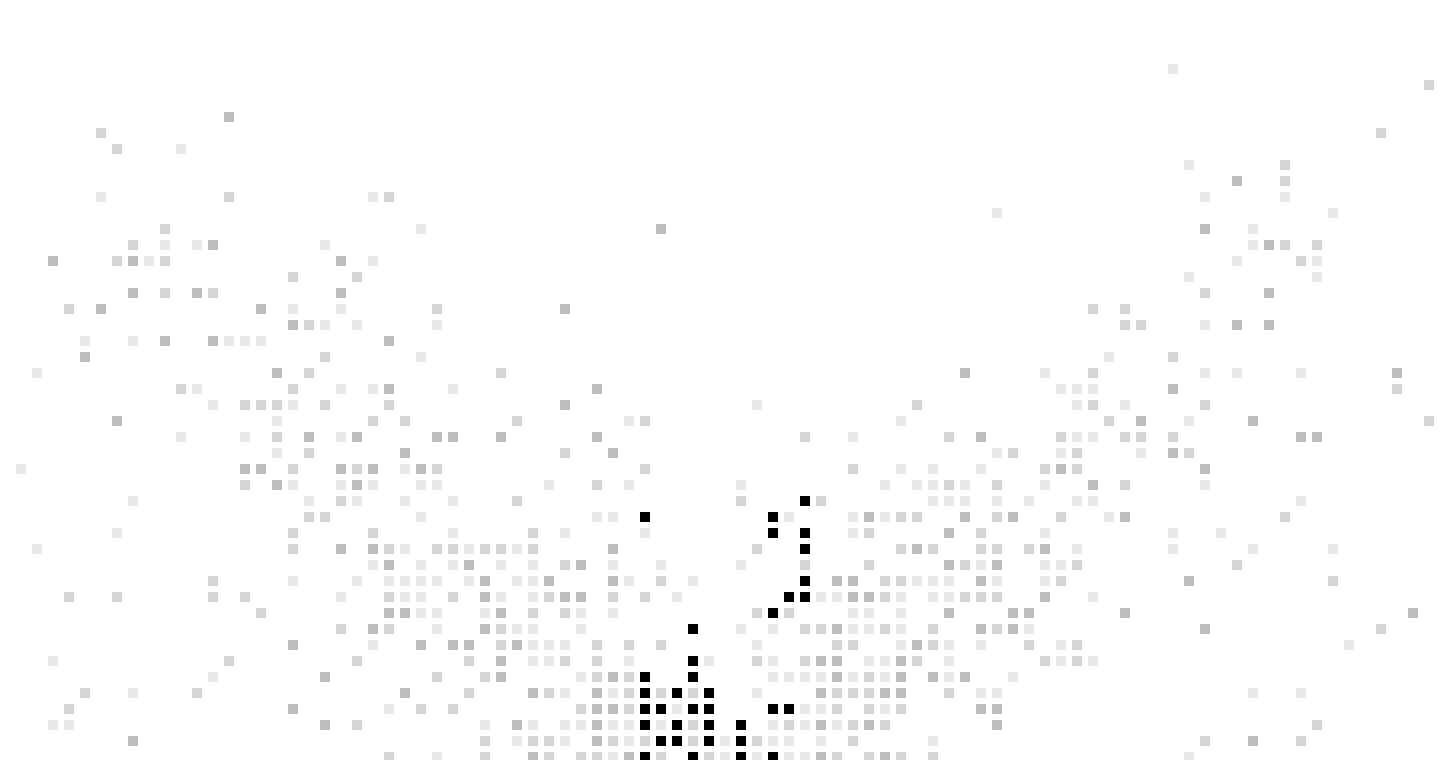
Each pile shows the results this test could have produced by chance. The less the piles overlap, the more confident you can be. Move left to see what the same rates would have told you with less data.
How to read your result
A significant result answers one question: is this gap likely to be real? These checks cover the mistakes that make a real-looking winner fail after launch.
What the p-value tells you
The p-value is the chance of seeing a gap this large if the change did nothing. A p-value of 0.03 means a 3% chance that random variation alone produced it. It is not the chance that version B is better, and it does not say how much better.
Significant is not the same as worth it
With enough traffic, a tiny difference becomes significant. Before you ship a winner, check the size of the gain against what the change costs to keep. If you sell something, compare revenue per visitor as well as conversion rate: a version can win on sign-ups and lose on sales.
Do not stop the first time it turns significant
Results swing early in a test. If you check every day and stop the first time the calculator shows 95%, your real false-positive rate is several times higher than 5%. Decide the sample size before you start, then read the result once you reach it.
Run full weeks
People behave differently on a Tuesday and a Saturday. Run every test for at least one full week, ideally two, even when you hit your sample size sooner, so each version sees the same mix of days.
Check the split before the result
If you set traffic to 50/50 and the visitor counts are far apart, something in the setup is broken: a redirect, a slow variant, a bot filter, a tracking gap. That is called a sample ratio mismatch, and it makes the result untrustworthy. The calculator flags it under the result.
Testing more than two versions
Every extra comparison is another chance to find a winner by accident. With three variants against one control, divide your threshold by three: p below 0.017 instead of 0.05. Compare each variant to the control here, one pair at a time.
Two-tailed, on purpose
This calculator runs a two-tailed test: it looks for a difference in either direction, so it also tells you when the new version is worse. A one-tailed test reaches significance sooner but cannot show a loss.
When to use a different test
This is a test for conversion rates: each visitor either converts or not. Revenue per visitor and average order value are not rates, so they need a t-test or a bootstrap, which handle a few large orders skewing the average.
How significance works
z = (rate B − rate A) ÷ standard error
How do I calculate statistical significance for an A/B test?
Enter visitors and conversions for the control and the variant. The calculator compares the two conversion rates with a two-proportion z-test and returns the p-value and confidence level.
Is it a 5% or a 95% significance level?
They are the same threshold seen from two sides. A 5% significance level (p below 0.05) is 95% confidence.
Is a p-value of 0.001 statistically significant?
Yes. It is far below the usual 0.05 cutoff, which is 99.9% confidence.
What confidence level should I use?
95% (p below 0.05) is the standard for A/B testing: a 5% chance that the result is random variation.
How many visitors do I need for 95% confidence?
It depends on your baseline conversion rate and the lift you want to detect. The sample size calculator gives the exact number per version.
What if my test is not significant?
You need more data. Check the sample size calculator, then let the test run its full duration.
Can I stop a test early if it is significant?
Stopping early raises false positives. Run the test for the duration the test duration calculator gives you.
What does a p-value of 0.05 mean?
If the change made no difference, you would see a gap at least this large about 5% of the time. It is the usual cutoff for calling an A/B test, equal to 95% confidence.
Why did my test go from significant to not significant?
Early results swing. A test that crosses 95% after a few days often falls back as more visitors arrive. That is why you set the sample size first and read the result only once you reach it.
What is sample ratio mismatch?
When the visitor counts in each version are further apart than the split you set allows by chance. It points to a setup problem, such as a redirect or tracking gap, and means the result should not be trusted until it is fixed.
Can I use this calculator for revenue?
No. It compares conversion rates. Revenue per visitor and average order value need a t-test or bootstrap. Use this calculator for purchases, sign-ups or clicks, where each visitor either converts or not.
Get real-time significance, automatically.
Humblytics calculates statistical significance continuously as your test runs, no manual number crunching. See live confidence levels, see when a winner emerges, and let your agent explain the results.
No card. Team plans from $79 a month. Book a demo